Data Science & Analytics Overview
Data Science & Analytics is the process of turning raw information into understanding that can guide decisions, reveal opportunities, and improve how organizations operate.
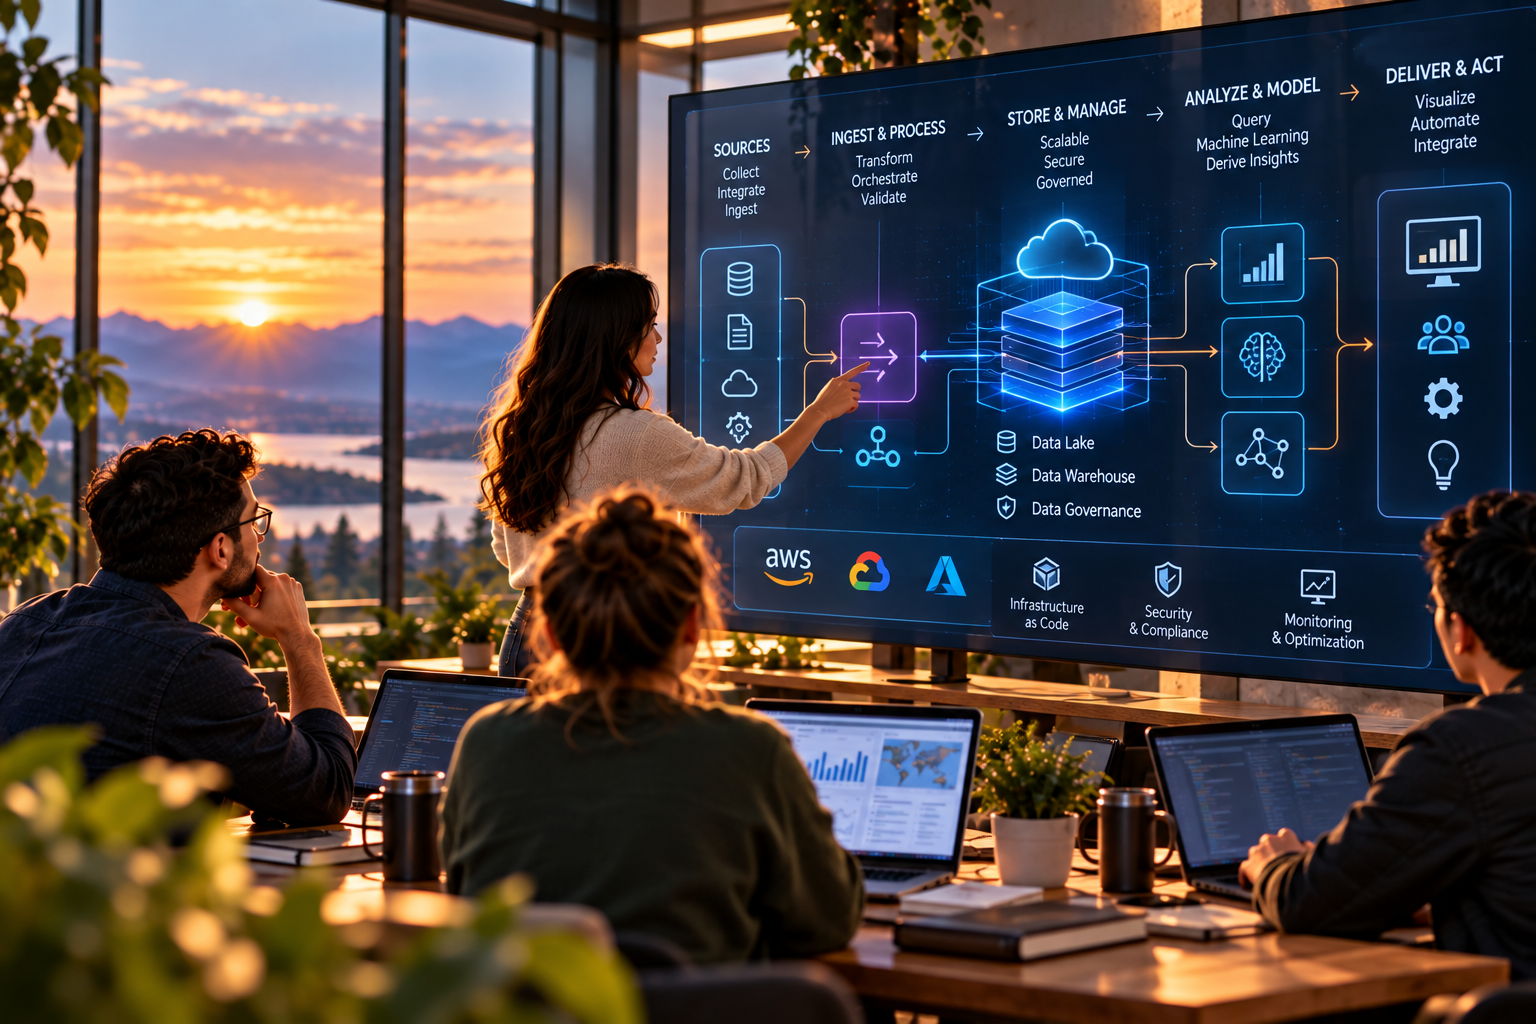
The work begins long before a dashboard, prediction, or machine-learning model is created. Data must first be collected, organized, cleaned, transformed, and understood. AspirationalX brings together data engineering, analytics, cloud infrastructure, and technical expertise to build that foundation and then use it to uncover meaningful patterns and insights.
Our experience spans the full data lifecycle, from developing scalable data pipelines and analytical environments to creating dashboards, predictive models, machine-learning solutions, and data-driven applications. We work across modern cloud and data platforms, including AWS, Google Cloud Platform, Databricks, Apache Spark, and related technologies, allowing us to design around the problem rather than a particular tool.
We also understand what it takes to move analytics beyond experimentation. Infrastructure, automation, scalability, cost, reliability, deployment, monitoring, and data quality all influence whether an analytical solution becomes something an organization can actually depend on.
The goal is not simply to analyze more data. It is to create a reliable path from raw information to understanding, from understanding to action, and from action to better decisions.
Typical Use Cases for Data Science & Analytics
- Exploratory data analysis — Examine complex datasets to identify patterns, relationships, anomalies, trends, and opportunities that may not otherwise be visible.
- Business intelligence and reporting — Transform organizational data into dashboards, reports, and metrics that provide clearer visibility into performance and operations.
- Predictive analytics — Use historical information and statistical techniques to estimate future outcomes, behaviors, risks, or opportunities.
- Machine learning — Develop models that identify patterns, make predictions, classify information, automate decisions, or improve as additional data becomes available.
- Data preparation and transformation — Clean, combine, structure, and enrich raw information so it can be reliably used for analysis.
- Data pipeline development — Build automated systems that continuously move information from its source into analytical and operational environments.
- Large-scale analytics — Analyze datasets that require distributed processing, cloud infrastructure, or specialized data platforms because of their size or complexity.
- Geospatial and behavioral analytics — Analyze location, movement, event, and behavioral data to better understand activity and relationships.
- Operational analytics — Use system and business data to identify bottlenecks, improve processes, monitor performance, and support day-to-day decision-making.
- Risk and opportunity modeling — Combine multiple sources of information to identify patterns that can help organizations evaluate risk or recognize potential opportunities.
- Data-driven product development — Incorporate analytics, recommendations, predictions, or other data-driven capabilities directly into software products and services.
- Analytics modernization — Replace spreadsheets, manual processes, fragmented reporting, or legacy analytical systems with scalable and repeatable data environments.
Our Expertise with Data Science & Analytics
AspirationalX brings experience across data science, data engineering, analytics, machine learning, cloud infrastructure, distributed computing, and software development.
Our work has involved datasets ranging from millions of individual records to hundreds of terabytes, including financial, operational, behavioral, geospatial, infrastructure, and other complex data. These environments often require more than simply selecting an analytical tool; they require designing the architecture and processes that allow information to be reliably collected, processed, understood, and used.
We work with technologies including AWS, Google Cloud Platform, Databricks, Apache Spark, BigQuery, data warehouses, data lakes, orchestration platforms, databases, APIs, visualization tools, and related cloud and analytics technologies.
Our experience also includes developing scalable ETL pipelines, performing large-scale geospatial analysis, supporting risk modeling, optimizing distributed processing workloads, developing analytical systems, and moving data processes from prototypes into reliable production environments.
Just as importantly, we consider how analytical systems will operate after they are built. Data quality, infrastructure cost, processing performance, automation, monitoring, documentation, maintainability, and the ability for people to understand the results all influence whether analytics actually creates value.
As machine learning and AI become increasingly accessible, having a strong data foundation becomes even more important. Models and analytical tools can only be as useful as the information, context, and systems supporting them.
Our focus is therefore not simply on producing another model, dashboard, or analysis. We build the data foundations, analytical systems, and processes that allow organizations to continuously learn from their information and put that knowledge to work.
Case Studies Featuring Data Science & Analytics
- Principal Component Analysis of Mobile Ad Engagement at Scale
- Big Data Exchange (BDEX) Customer Revisit Likelihood Scoring Algorithm Leveraging Location Data
- Enhancing Utility Pole Maintenance with Advanced Data Analytics
- Developing an Advanced Analytics Application for a U.S. Government Client
- Transforming City Property Data into Actionable Geospatial Intelligence for St. Louis
- High-Volume Real-Time Data Processing and Analytics System
- Scaling Smarter: Reducing Analytics Costs with a Query Viability Layer