Data Warehousing Overview
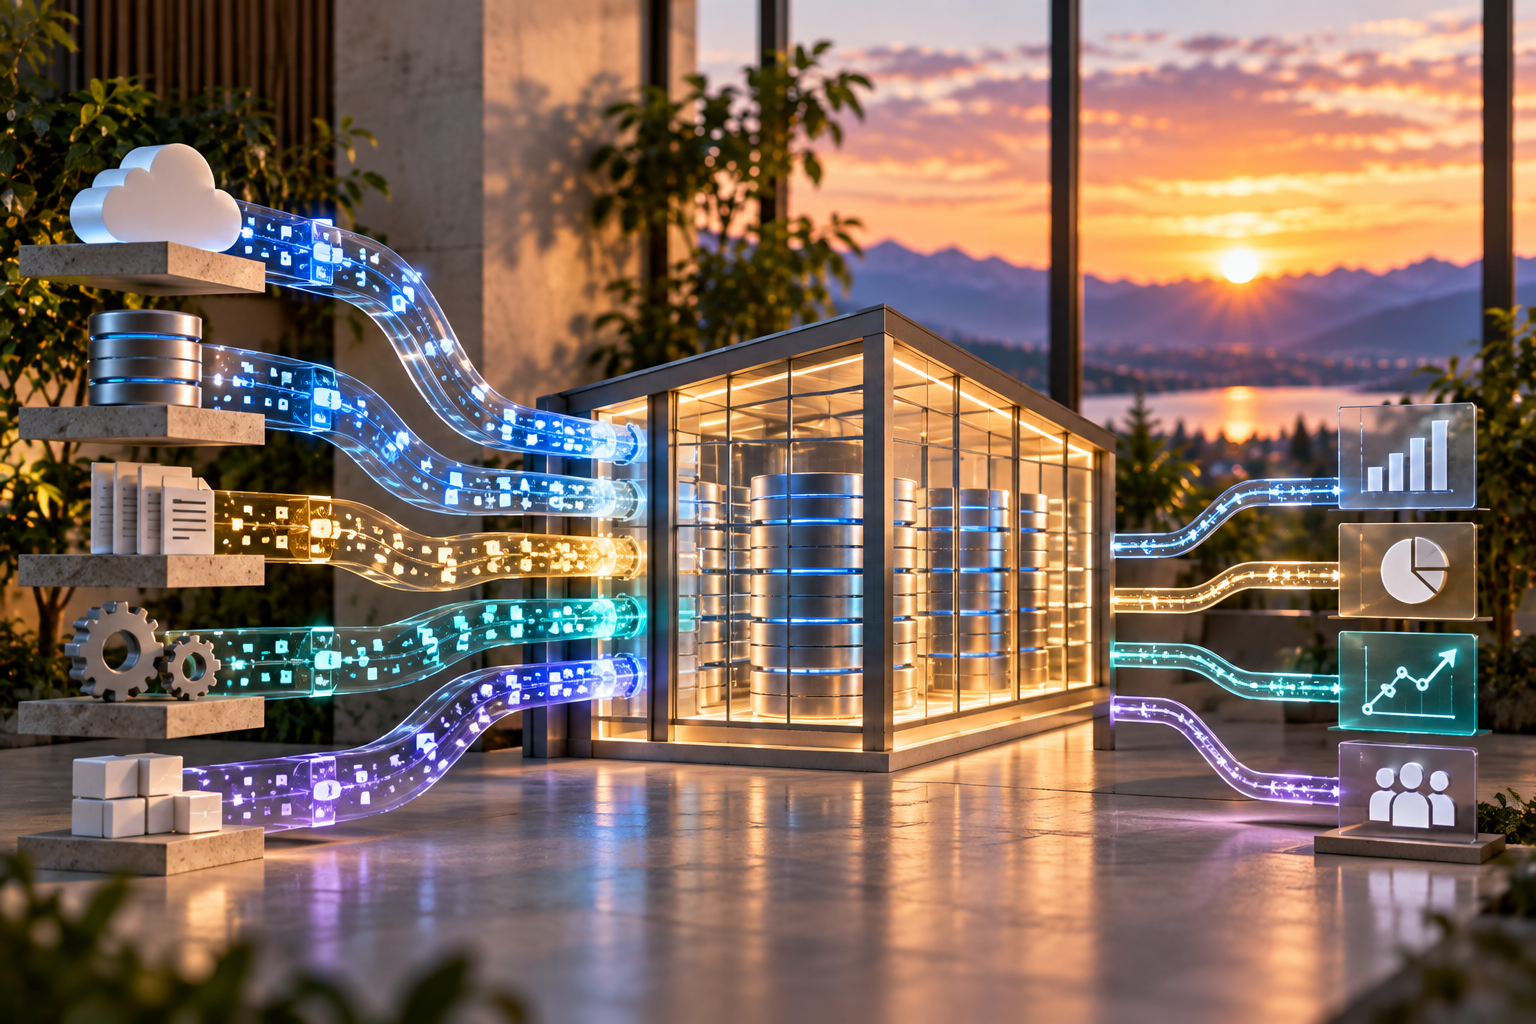
Organizations often have valuable data spread across applications, databases, cloud platforms, vendors, operational systems, and other sources. Data warehousing brings that information together into a structured environment where it can be consistently organized, analyzed, and used across the organization.
AspirationalX designs and builds data warehouses that create a reliable foundation for reporting, analytics, machine learning, and data-driven applications. Our work spans the full data warehousing lifecycle, from understanding where information originates and how it will be used to designing the architecture that collects, transforms, stores, and makes that information accessible.
That often includes connecting multiple data sources, building ETL and ELT pipelines, transforming and modeling information, establishing historical records, and designing storage structures that make large datasets easier and more efficient to query.
But moving information into one location is only part of the challenge. Data quality, consistency, lineage, governance, performance, documentation, access, scalability, and infrastructure cost all influence whether a warehouse becomes a trusted business resource or simply another place where data accumulates.
We design data environments around how information will ultimately be used. That might mean supporting executive reporting and business intelligence, enabling analysts to explore information more independently, powering customer-facing applications, preparing datasets for machine learning and AI, or providing a shared data foundation across multiple parts of an organization.
The goal is to turn scattered information into an organized, trusted, and scalable source of data that people and systems can reliably use to understand what is happening and make better decisions.
Typical Use Cases for Data Warehousing
- Centralized organizational data — Bring information from multiple applications, databases, vendors, and business systems into a common environment for analysis and reporting.
- Business intelligence and reporting — Create trusted datasets that support dashboards, recurring reports, performance metrics, and organizational decision-making.
- ETL and ELT pipelines — Build automated processes that extract, load, clean, transform, enrich, and organize information from multiple sources.
- Historical data analysis — Preserve information over time so organizations can identify trends, compare performance, and understand how conditions have changed.
- Cross-system analysis — Connect information that previously lived in separate systems to reveal relationships and provide a more complete view of the organization.
- Data integration — Standardize information from different sources, formats, vendors, or platforms so it can be analyzed consistently.
- Analytics and data science foundations — Prepare reliable datasets for advanced analytics, predictive modeling, experimentation, and machine learning.
- Self-service analytics — Give analysts and business teams greater access to trusted, organized information without requiring engineering work for every question.
- Application and product data — Provide centralized data that can support APIs, customer-facing applications, internal tools, recommendations, and other data-driven products.
- Data platform modernization — Replace fragmented, manual, legacy, or difficult-to-maintain data environments with scalable cloud-based architecture.
- Large-scale data management — Store and organize datasets that have grown beyond the practical limits of traditional databases or individual applications.
- Data quality and consistency — Establish transformation and validation processes that improve the reliability of information used throughout the organization.
- Performance optimization — Structure data and queries so analytical workloads can operate efficiently as data volumes and usage increase.
- AI and machine-learning readiness — Build organized and accessible data foundations that can support machine-learning models and emerging AI applications.
Our Expertise with Data Warehousing
AspirationalX brings experience designing, building, modernizing, and operating data environments across cloud infrastructure, data engineering, distributed processing, analytics, and software development.
Our work has involved data environments ranging from millions of individual records to hundreds of terabytes, including systems where information originates from applications, APIs, databases, third-party vendors, event streams, geospatial datasets, and other large-scale sources.
We work across technologies and platforms including AWS, Google Cloud Platform, BigQuery, Databricks, Apache Spark, cloud object storage, relational databases, orchestration platforms such as Apache Airflow, APIs, analytics tools, and related data infrastructure.
Our experience includes building ingestion and transformation pipelines, developing cloud-based data warehouses, organizing large proprietary datasets, processing high-volume location and behavioral information, creating data foundations for analytical applications, and improving the performance and cost of existing data environments.
We also understand that a warehouse exists within a larger ecosystem. Information must move reliably from its source into the warehouse, transformations must be understandable and maintainable, downstream systems must be able to access it efficiently, and teams need documentation that explains what the data represents and how it should be used.
As data environments grow, architecture decisions increasingly affect both performance and cost. Storage design, processing patterns, query behavior, orchestration, data retention, and the frequency at which information is transformed can significantly influence how efficiently a platform operates.
The same foundation is becoming increasingly important as organizations adopt machine learning and AI. Before advanced tools can reliably answer questions or automate decisions, the underlying information must be accessible, organized, contextualized, and trustworthy.
Our focus is therefore not simply on collecting more information. We build data environments that transform information from many disconnected sources into a reliable organizational resource that can continue creating value as the business and its data grow.